
Blog
Notes from the frontier.
Talks, results, and what we learn making inference faster and cheaper on real workloads.
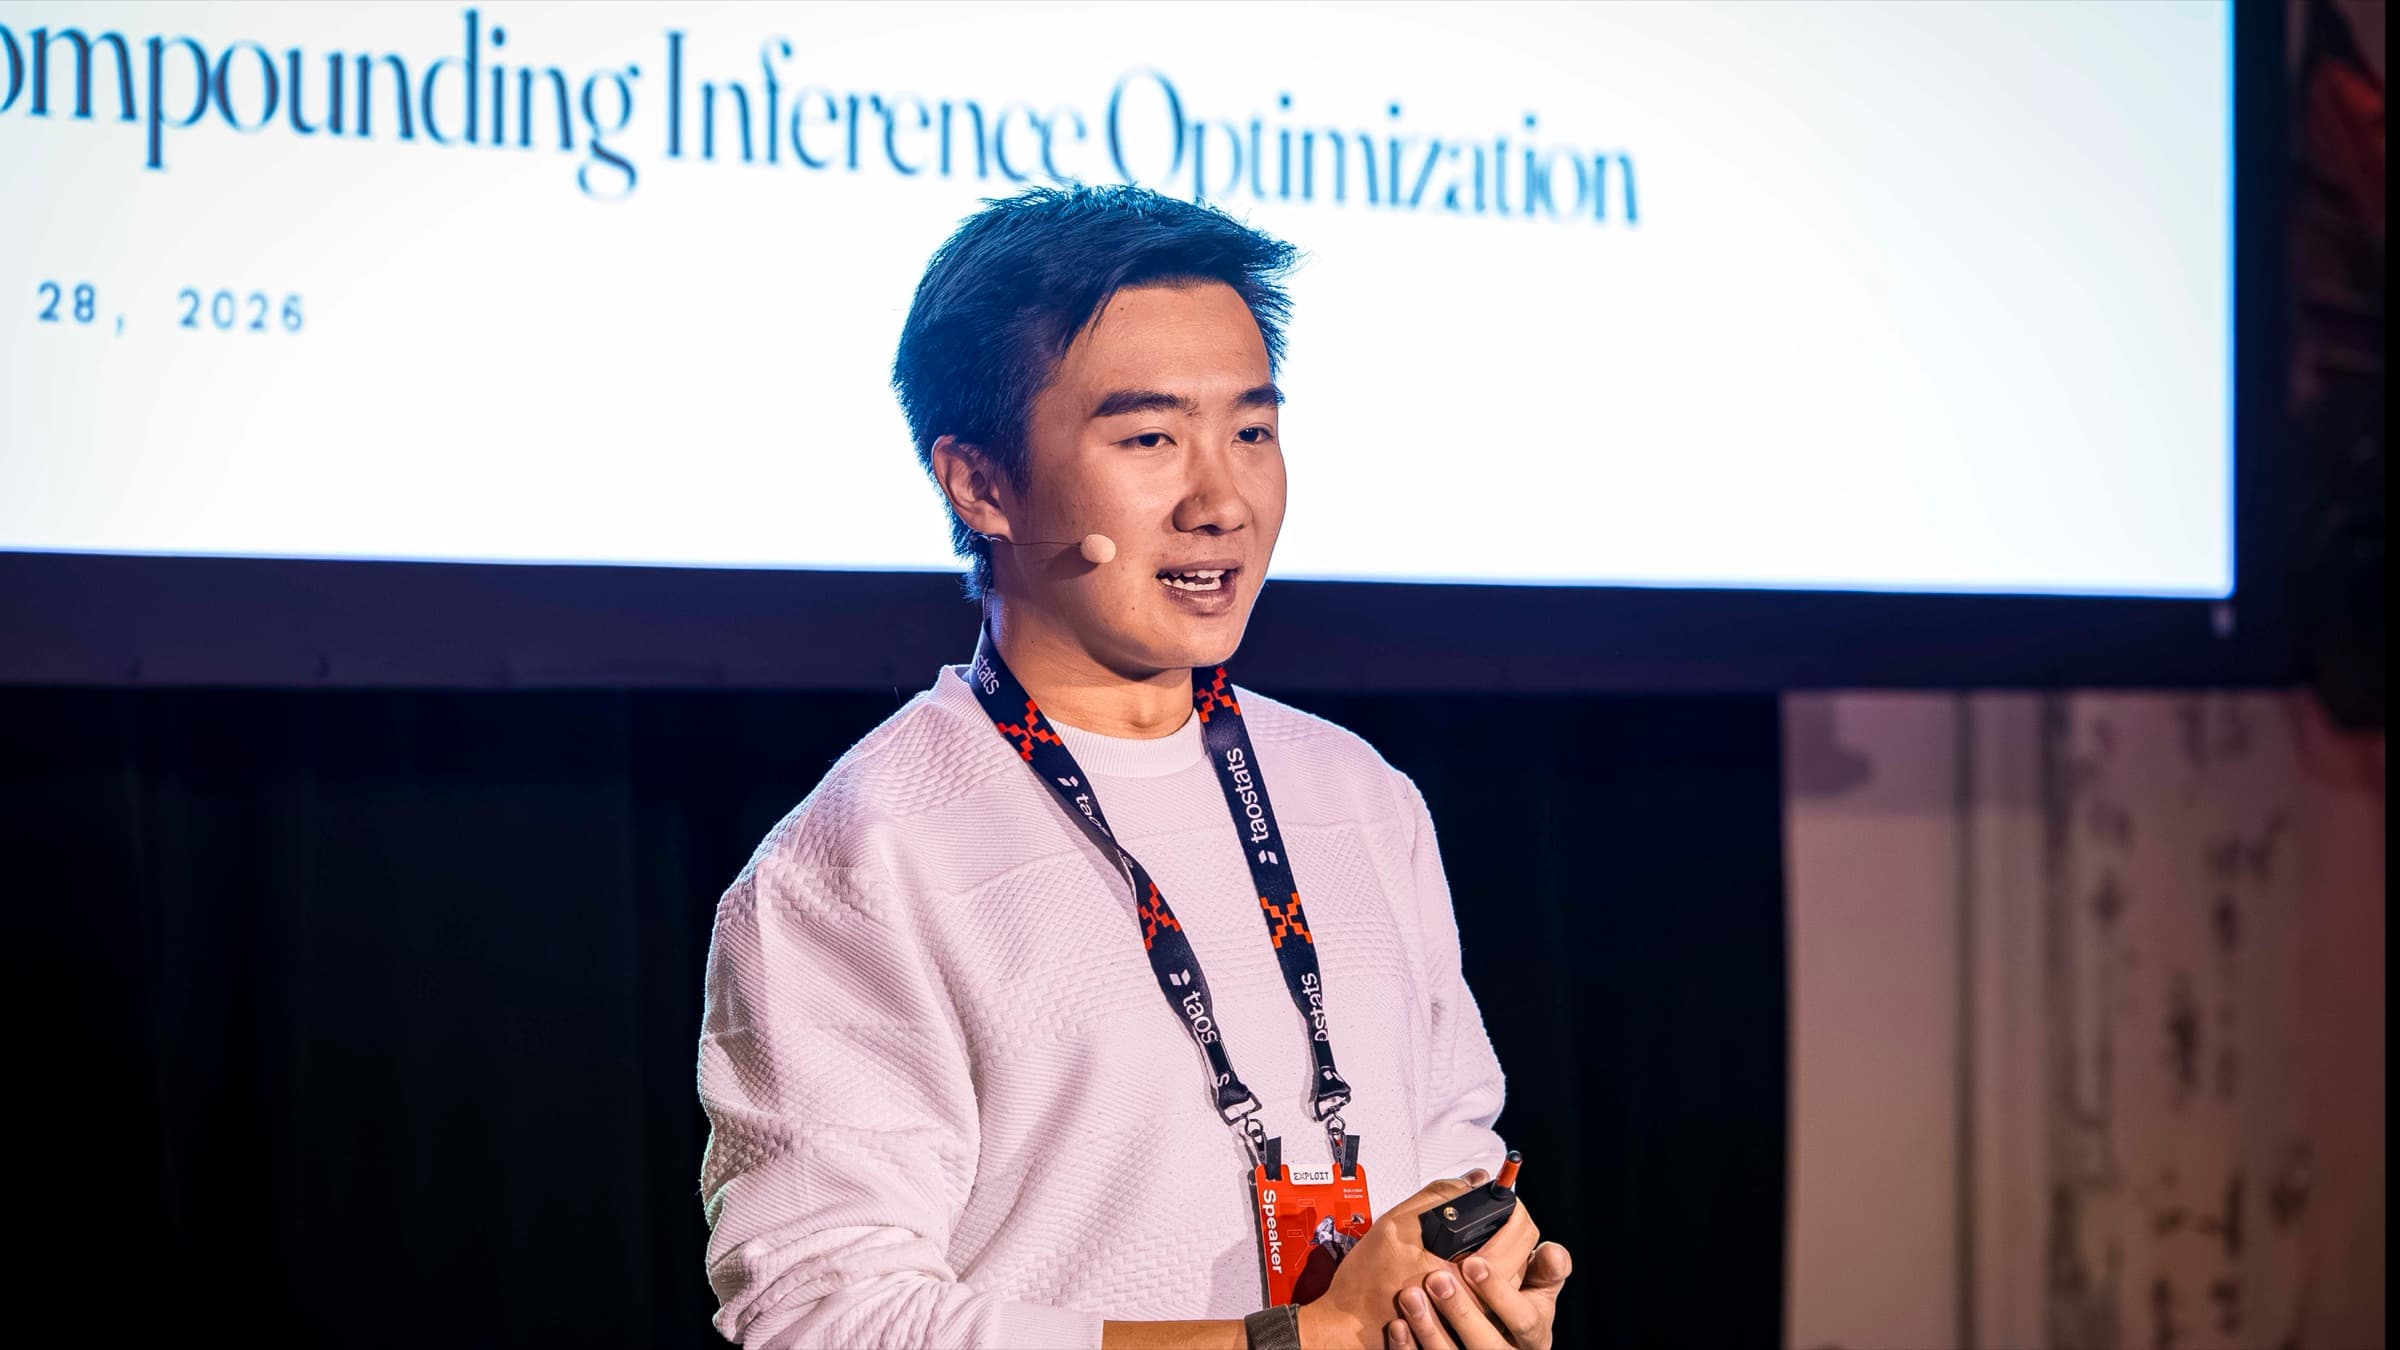
The pit crew, not the engine
Notes from Xavier Lyu's talk at Exploit Summit in Montréal: why inference gains compound, and why they only count on the workload you already run.
Read · 5 min
Pareton joins Liquid Inference as a verified provider
Inference is turning into a market with live prices. On a market like that, cost per token is the whole game.
Engy is getting faster
Three rounds into our Kimi K3 campaign, the leading patch serves Engy's traffic about 25% faster end-to-end, on the same eight B300 GPUs.
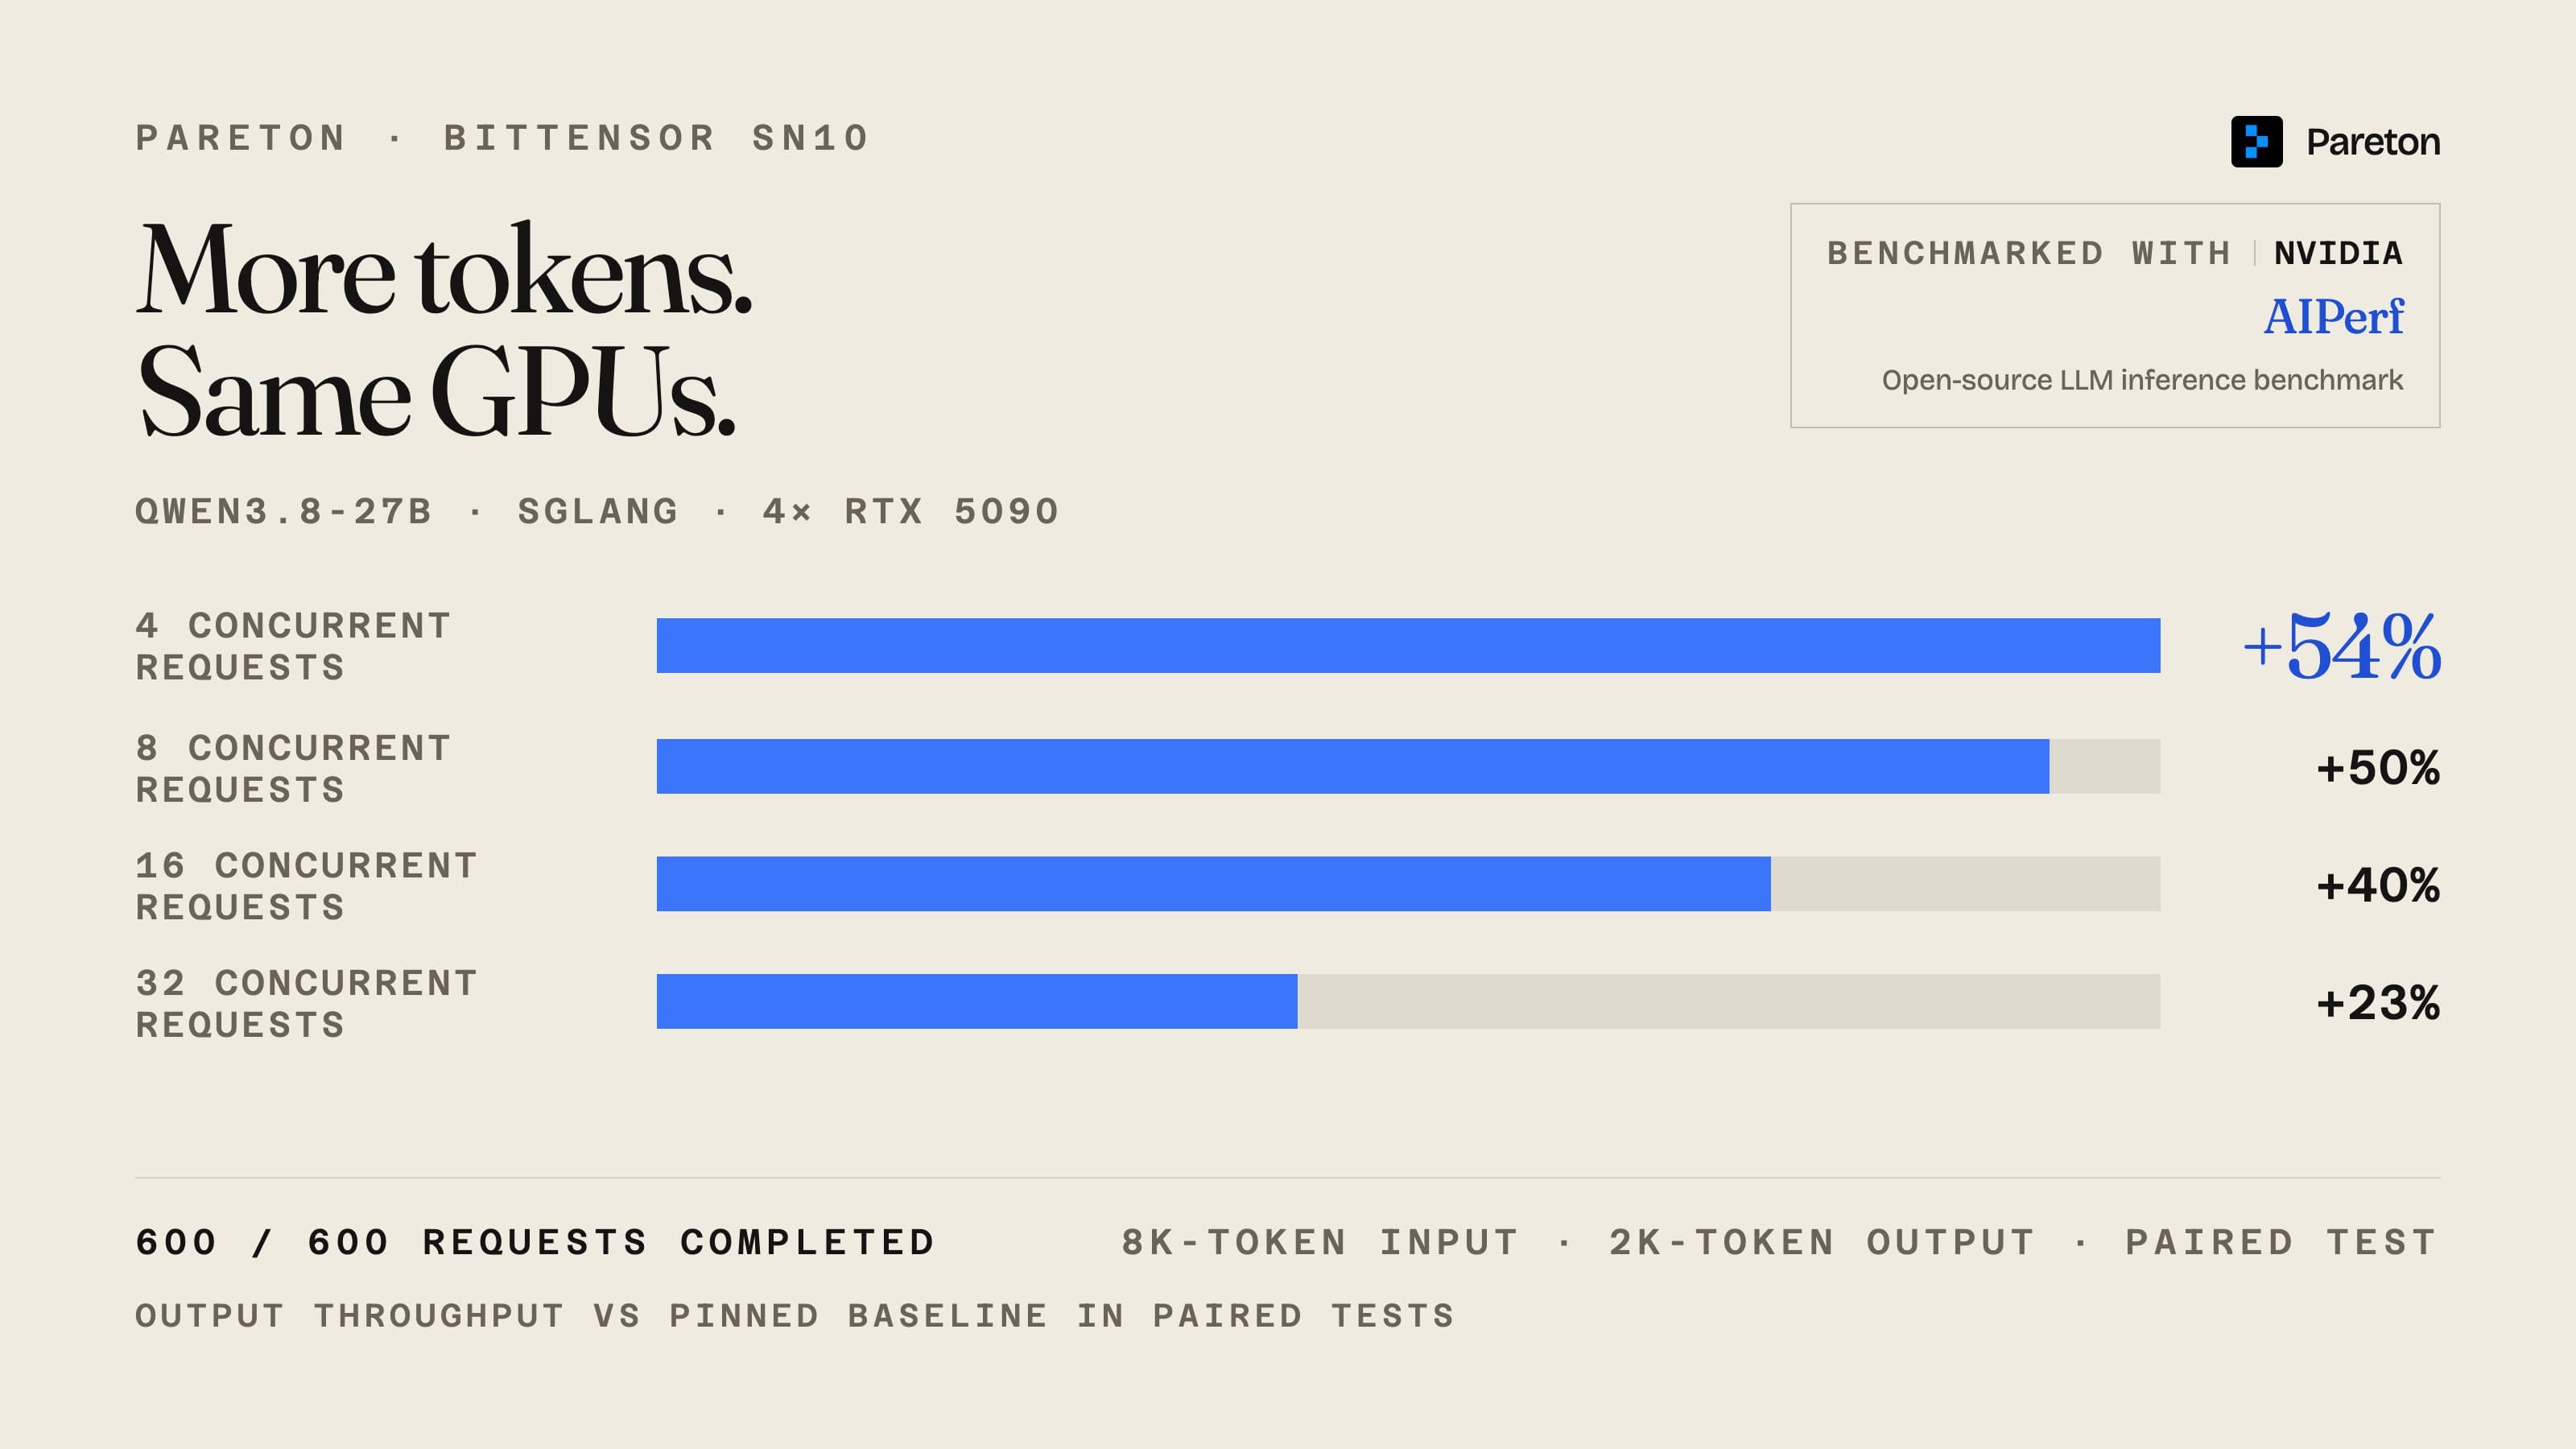
Same model. Same GPUs. Up to 54% more tokens per second.
We benchmarked the top miner patch for Qwen3.8-27B against the pinned baseline with NVIDIA's AIPerf. Output throughput rose 23 to 54% across every load we tested.
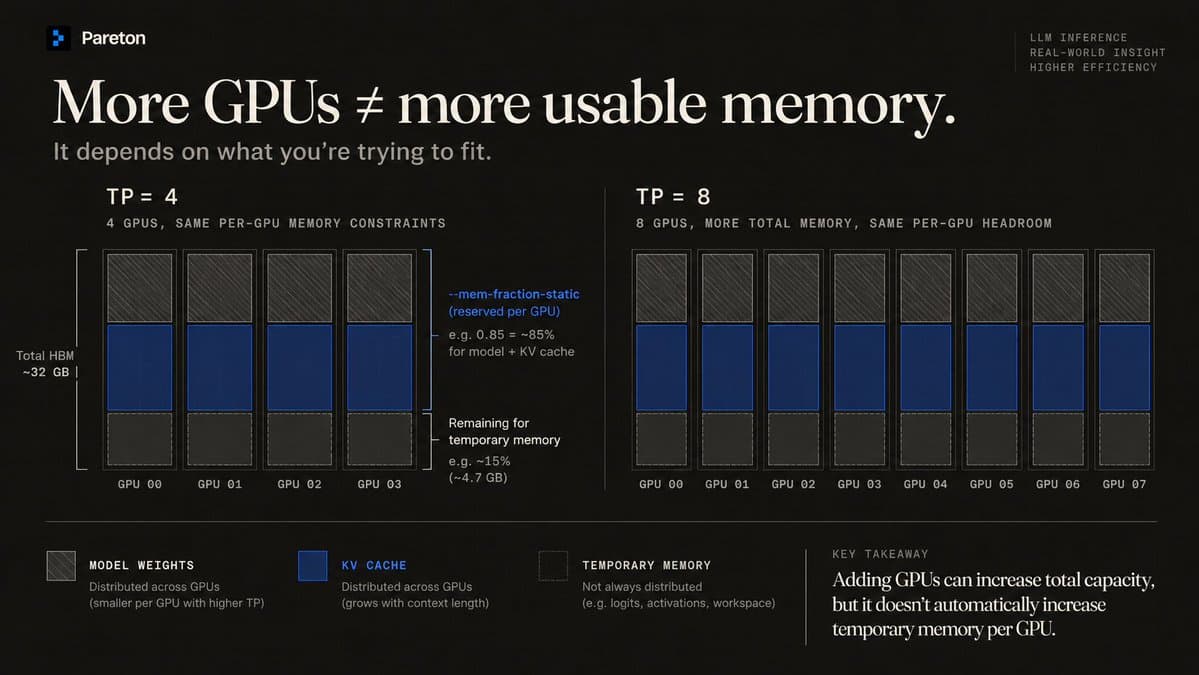
More GPUs don't always mean more usable memory
A workload hit an out-of-memory error. Doubling the GPUs would not have fixed it. Here is why, and what did.